Every AI vendor demo looks impressive. The question is whether it solves your problem or theirs. Here's how to evaluate AI tools before you commit, when only 13% of CIOs say AI has delivered significant value (Gartner, 2026).
The short version: here is how to evaluate AI tools without getting sold. Write your scoring rules before the first demo, test with your own messy data, and get the full cost and the data terms in writing. In Gartner's October 2026 survey of 2,002 CIOs, only 13% said AI had delivered significant or transformational value, so the burden of proof sits with the vendor.
Ask which model sits underneath the product, and which version.
Ask for accuracy on production data, and how it was measured.
Test your hardest cases, not the vendor's sample set.
Price twelve months: license, usage, integration, training and your team's time.
Get data retention, model training use and exit terms into the contract.
Every AI vendor demo looks incredible. The product finds the signal in your messy data, surfaces an insight nobody saw, and saves 40 hours a week. The slide deck practically hums. You leave the meeting thinking this might be the thing that changes everything.
Then you sign the contract, feed it your actual data, and discover the demo was running on a curated dataset that has almost nothing in common with your operations. The "40 hours a week" number was aspirational math. And the integration your team was promised takes four months and a consultant.
This pattern is well documented. Gartner's 2027 CIO and Technology Executive Agenda survey, published in October 2026, found that only 13% of CIOs say their enterprise has realized significant or transformational value from AI, and the likelihood of any one use case succeeding is still one in five. The gap between demo and deployment is the most expensive distance in enterprise technology right now.
The good news: you can close that gap before you spend anything. It takes a framework, not a leap of faith.
A demo shows the room the vendor furnished. Learning how to evaluate AI tools starts with bringing your own data and seeing what's actually there.
The red flags that save you money
Before you evaluate what a tool can do, evaluate who's selling it to you. Three red flags should end the conversation early, or at least move it from "buying" mode to "interrogating" mode.
They can't explain what model they use
"Proprietary AI" is a marketing term rather than a model architecture. Any vendor building on top of foundation models (and most are) should be able to tell you which model, what version, and how they've customized it. If the answer is vague ("we use advanced machine learning" or "our proprietary algorithms"), they're either reselling a wrapper around an API they don't control, or they don't understand their own product well enough to support it when something breaks.
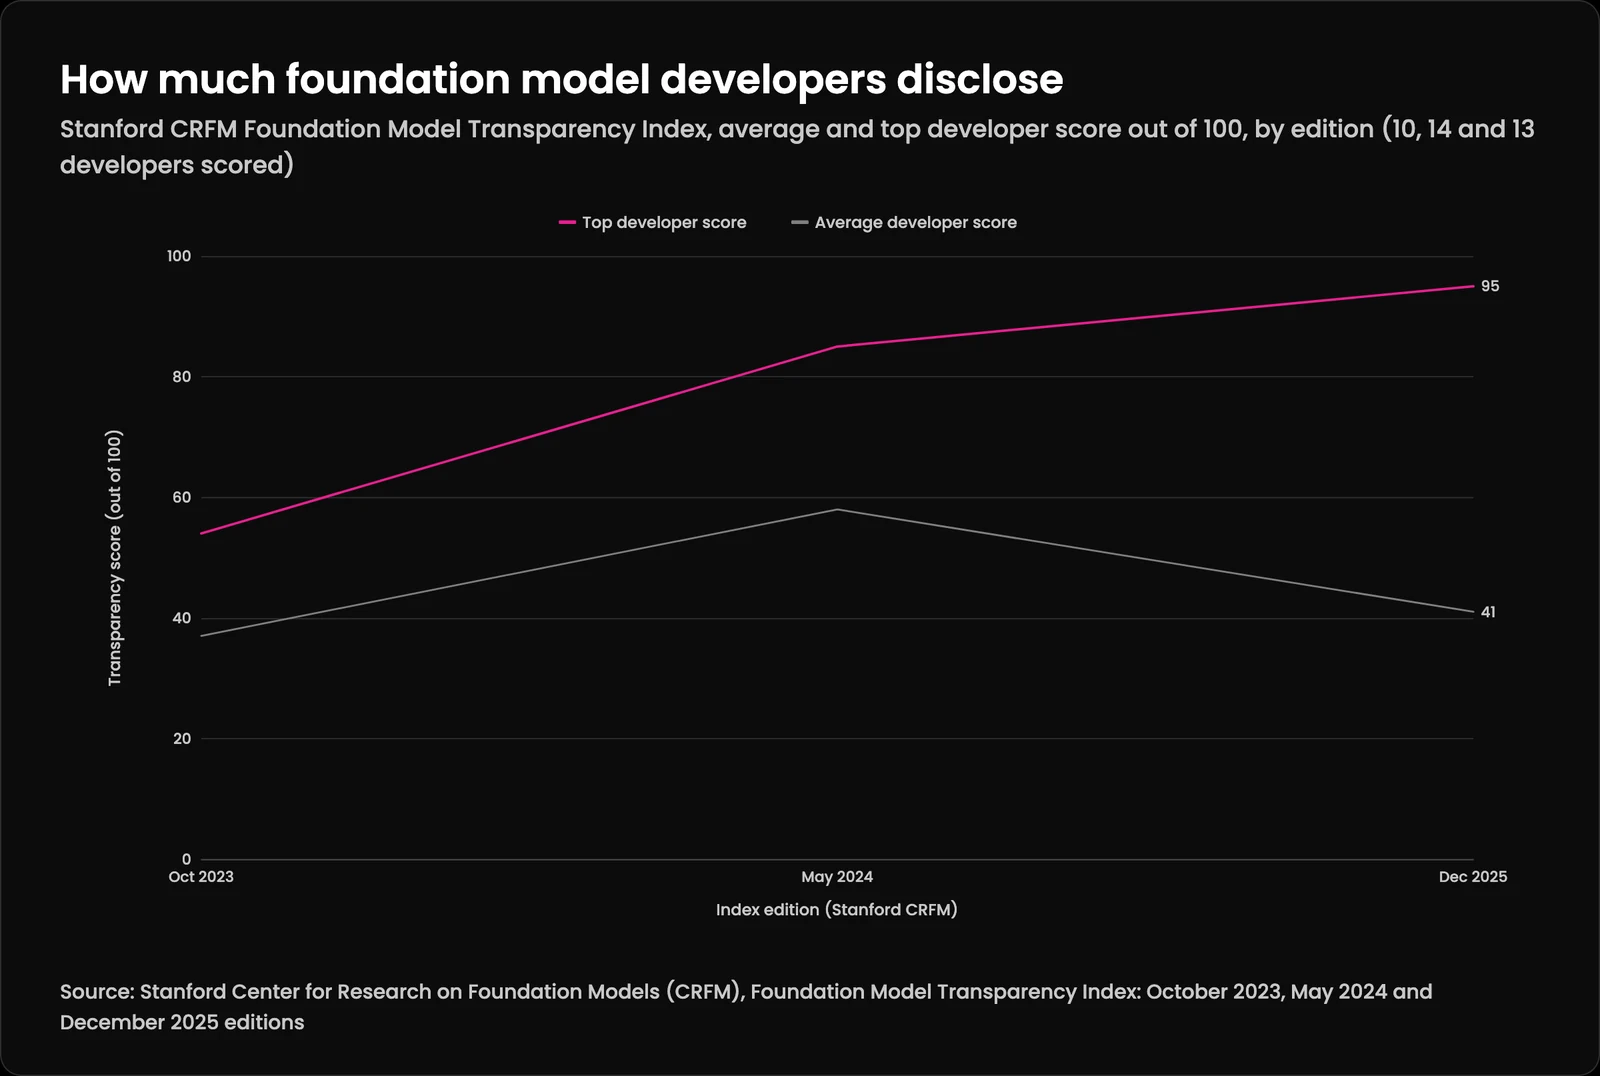
This matters because model selection determines capability limits, cost structure, data handling, and update cadence. A tool built on GPT-4o behaves differently than one built on Claude or Gemini or a fine-tuned open-source model. You need to know what's under the hood to evaluate whether it's appropriate for your data, your regulatory environment, and your risk tolerance. Developers also differ in how much they disclose: the average score in Stanford's Foundation Model Transparency Index was 41 out of 100 in December 2025, down from 58 in May 2024.
The best-scoring developer kept improving while the average fell back, so disclosure depends heavily on which model sits under a product.
How much foundation model developers disclose (Stanford Center for Research on Foundation Models (CRFM), Foundation Model Transparency Index: October 2023, May 2024 and December 2025 editions)
Index edition
Top developer score
Average developer score
Oct 2023
54
37
May 2024
85
58
Dec 2025
95
41
They have no accuracy data
Ask the vendor: "What's your accuracy rate on production data?" If they can't answer with a number and a methodology, that's a problem. If they give you a number but can't explain how they measured it (benchmark dataset, production sample, edge case coverage), that number is meaningless.
MIT Sloan Management Review published research from an 11-month study of five AI tools piloted at a leading health care organization: impressive performance results had been promised for each, and several did extremely poorly in their pilots. The authors' advice is to examine the tool's ground truth, the labeled data its accuracy was measured against, before you trust the number.
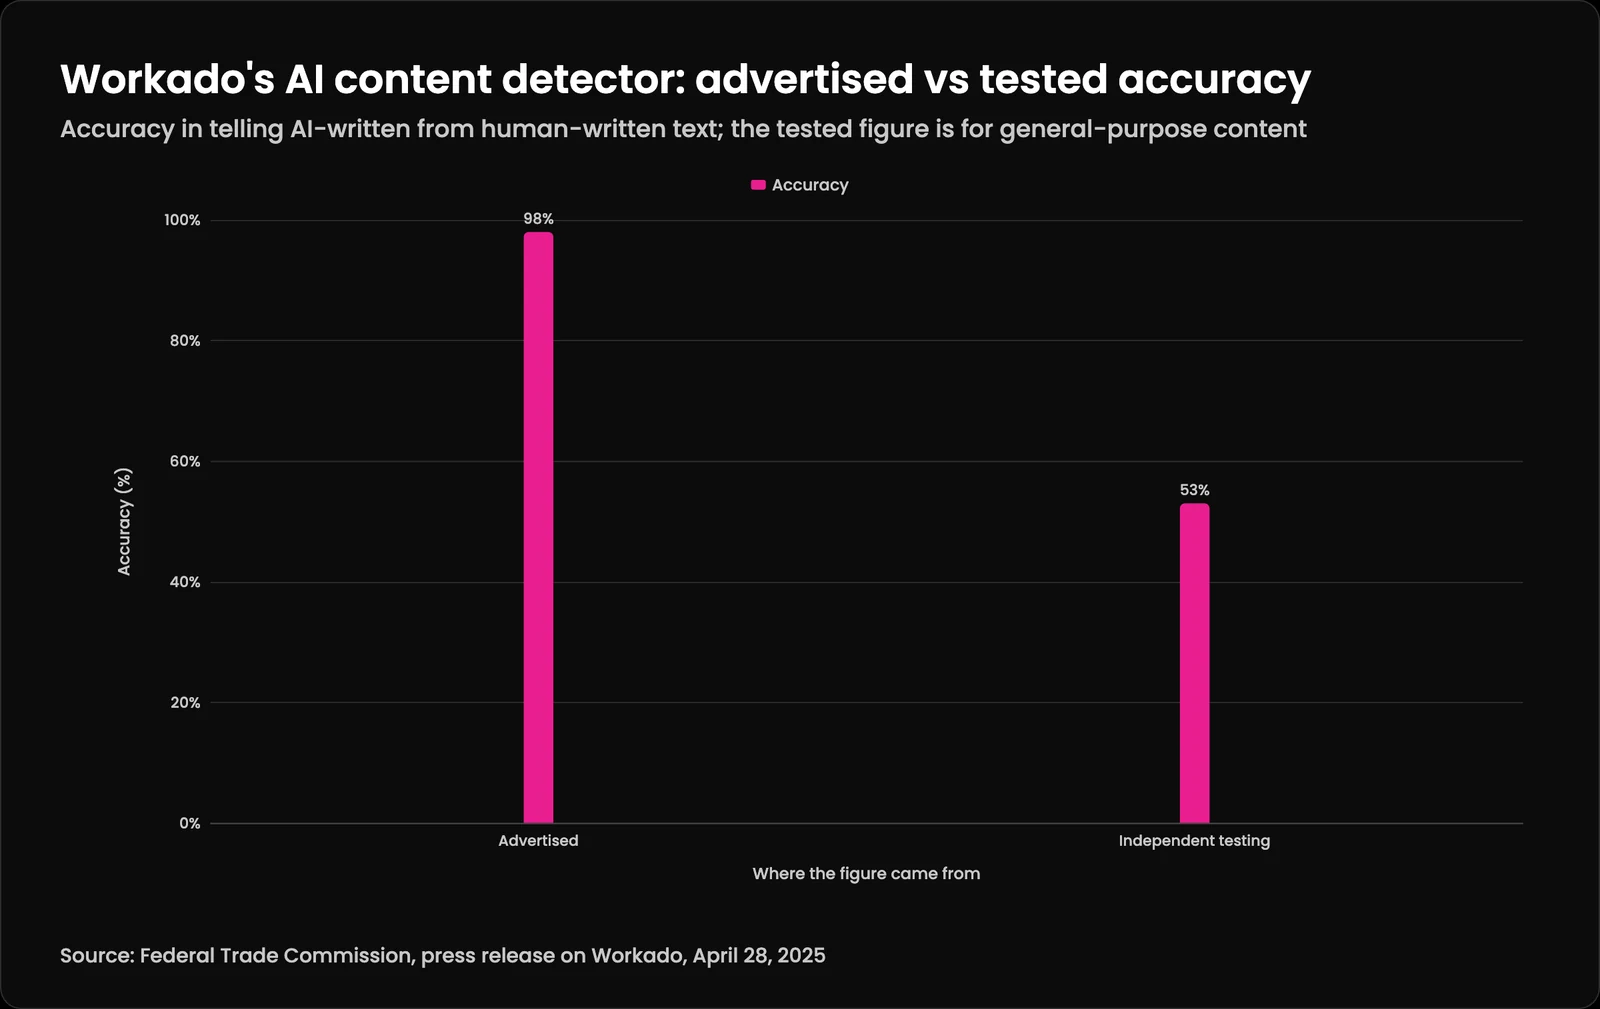
Regulators treat an accuracy number as a claim that needs evidence. In August 2025 the FTC finalized an order against Workado, which, according to the FTC, had advertised its AI content detector as 98 percent accurate when independent testing put it at 53 percent on general-purpose content. The order bars accuracy claims the company can't back with competent and reliable evidence.
Testing a vendor's number yourself is how to evaluate AI tools: the FTC said Workado advertised 98% accuracy, and independent testing found 53%.
Workado's AI content detector: advertised vs tested accuracy (Federal Trade Commission, press release on Workado, April 28, 2025)
Accuracy figure
Accuracy
Advertised
98%
Independent testing
53%
The demo uses cherry-picked examples
Every demo shows the happy path. The system classifies the document correctly, extracts the right fields, generates the right summary. But the question that separates a useful tool from an expensive disappointment is: what happens on the 20% of inputs that don't look like the training data?
Ask to see the failure mode. Ask what happens when the model is wrong. Ask what confidence scoring looks like. If the vendor can't show you a graceful failure (if the demo environment doesn't even have a mechanism for flagging low-confidence outputs), the tool was built to impress buyers, not to serve operators.
What to actually test
If a vendor survives the red flag check, the next step is hands-on evaluation with your data instead of theirs.
Your data, not their demo data
The single most important thing you can do during an AI evaluation is run the tool against your own production data. Not a sample the vendor prepared. Not a "getting started" dataset. Your actual, messy, inconsistent, real-world data: the data the tool will need to handle every day once you're paying for it.
This is where most demos fall apart. The vendor's sample data is clean, consistently formatted, and representative of the cases where the model performs best. Your data has edge cases, inconsistent naming conventions, missing fields, and formats that haven't been updated since your last CRM migration. If you wrote about this in the context of figuring out where AI fits in your business, data readiness was the prerequisite. It's also the best evaluation tool you have.
Edge cases, not happy path
Deliberately feed the tool the hardest inputs you have. The documents with unusual formatting. The records with missing fields. The queries that your own team gets wrong 10% of the time. If the AI tool can't handle the cases that are hard for humans, you need to know that before you've committed budget.
This also reveals how the tool handles uncertainty. A well-built AI system signals its confidence along with its answers. It should be able to say "I'm not sure about this one" in a way that routes the input to a human reviewer. A tool that's always confident is a tool that's hiding its errors.
What happens when the model is wrong
This is the question that separates mature AI products from demo-ware. Every model produces incorrect outputs. The question is what the system does about it.
Does it flag low-confidence results? Does it maintain an audit trail? Can a human override the output and feed that correction back into the system? Is there a monitoring dashboard that tracks accuracy over time so you can see degradation before it causes problems?
After running your evaluation, score the tool against four strategic questions. You can answer them in a meeting without an engineering degree.
1. Does it solve a problem I already identified?
If you can't point to a specific, measurable problem this tool addresses, you're buying a solution looking for a problem. That's how generic comparisons lead to generic purchases. The tool should map directly to a pain point your team has already documented, not a pain point the vendor identified during the sales process.
2. Does it integrate with what I already use?
Integration cost is where AI budgets go to die. A tool that requires you to rebuild your data pipeline, retrain your team on a new interface, or hire a systems integrator to connect it to your existing stack can turn what looks like a $50,000 purchase into, for example, a $200,000 one with a 6-month timeline and an organizational change management problem on top.
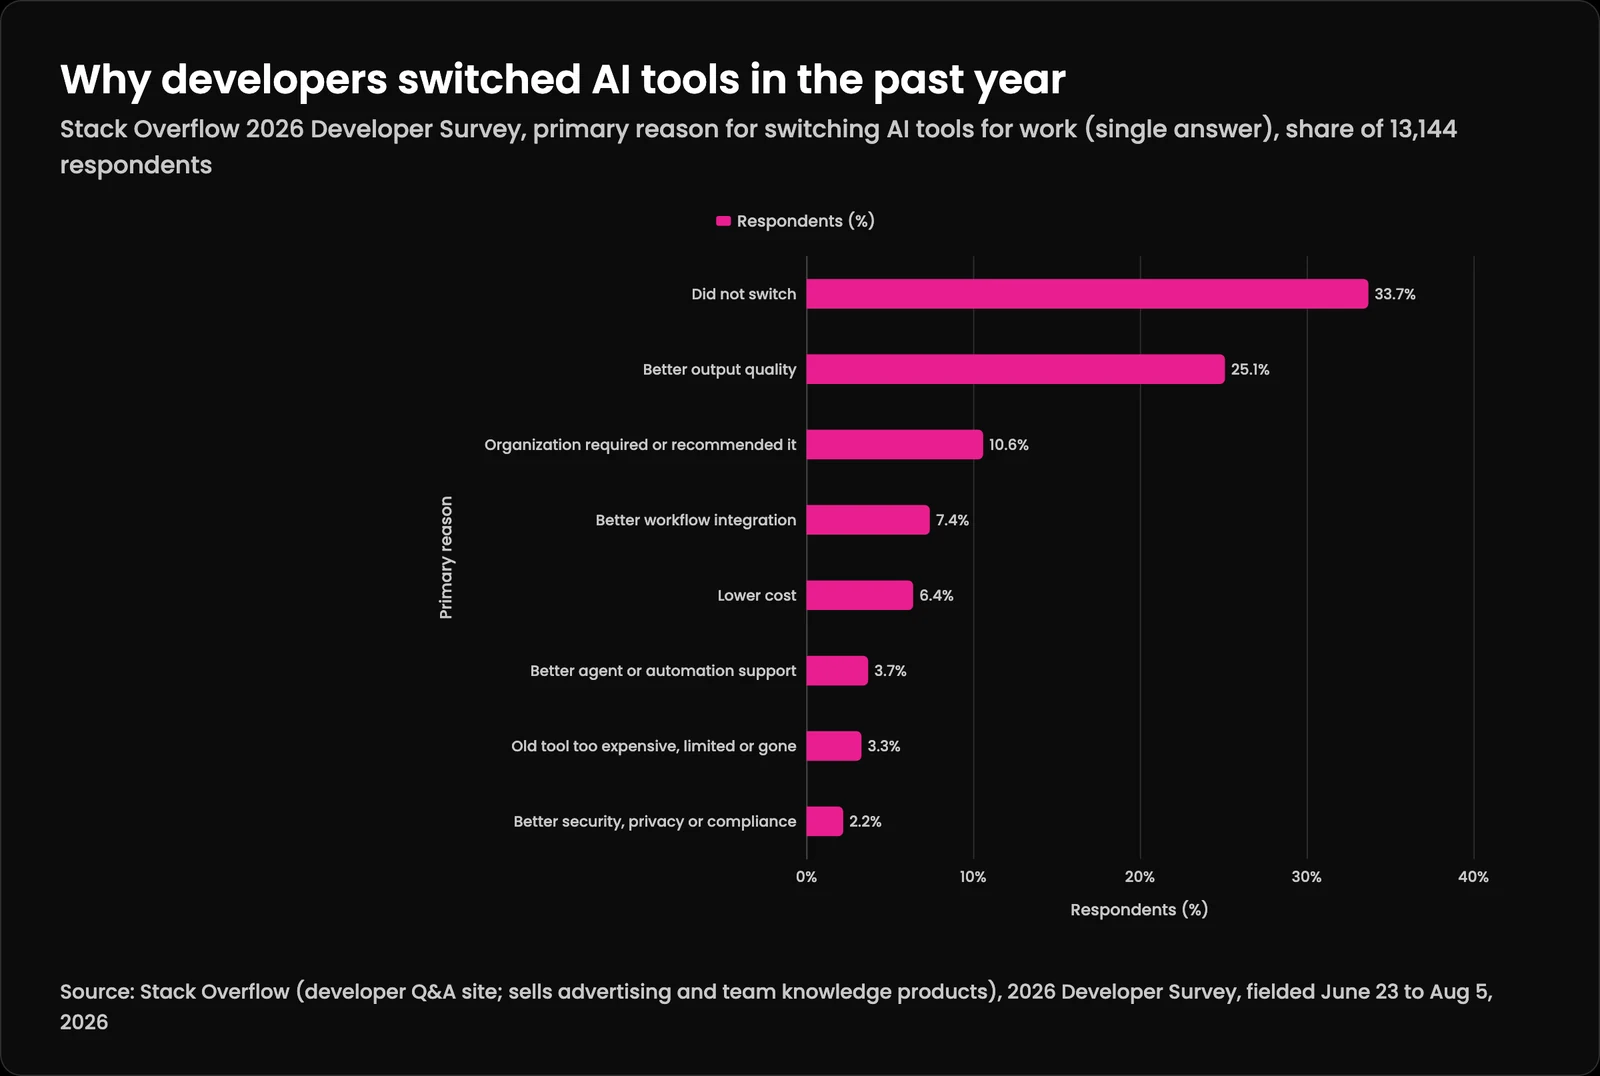
Ask specifically: what APIs does it expose? What formats does it accept? Does it work with your existing authentication? Can your team maintain the integration without the vendor's professional services arm? In Stack Overflow's 2026 Developer Survey, 25.1% of 13,144 respondents had switched AI tools for work in the past year mainly for better output quality, and 7.4% mainly for better workflow integration.
Output quality drove more switches than cost, integration and security combined among respondents to Stack Overflow's 2026 survey.
Why developers switched AI tools in the past year (Stack Overflow (developer Q&A site; sells advertising and team knowledge products), 2026 Developer Survey, fielded June 23 to Aug 5, 2026)
Primary reason
Respondents (%)
Did not switch
33.7%
Better output quality
25.1%
Organization required or recommended it
10.6%
Better workflow integration
7.4%
Lower cost
6.4%
Better agent or automation support
3.7%
Old tool too expensive, limited or gone
3.3%
Better security, privacy or compliance
2.2%
3. What's the real total cost?
License fees are the visible cost. The real cost includes: implementation, integration, training, ongoing API/compute charges (many AI tools bill per query or per token), maintenance, and the opportunity cost of your team's time during rollout. Get a 12-month total cost projection that includes all of these. If the vendor can't produce one, they either don't know or don't want you to.
The people running these budgets expect the cost to climb: in Gartner's October 2026 CIO survey, 51% of CIOs said they expect AI to increase the total cost of ownership of technology solutions, and 58% reported more pressure to deliver cost improvement from AI.
4. What happens to my data?
This is the question most buyers skip, and it's the one with the longest tail of consequences. Where does your data go when the tool processes it? Is it stored? For how long? Is it used to train or improve the vendor's model? Can you get it back if you cancel? What jurisdiction is it stored in?
For regulated industries, these questions are compliance requirements. But even for non-regulated companies, data handling terms determine your exposure. A vendor that uses your customer data to train their model is improving their product with your competitive advantage. That's a strategic cost that doesn't show up on an invoice.
How to evaluate AI tools before you buy: a pilot in four steps
The scorecard tells you what to judge. A short pilot tells you how. This is the sequence I use to show a business how to evaluate AI tools before signing a contract, whether the tool drafts support replies, reads invoices or scores sales leads.
Write the rubric first. Before the first vendor call, write down the problem, the number that would prove the tool helped (minutes per ticket, error rate, cost per document) and the result that would make you walk away. Gartner found that only 31% of CIOs have rules for stopping AI pilots, and organizations with guidelines for when a pilot should not move to production are 2.3 times more likely to be among its top performers, in the same 2026 CIO survey.
Build a test set from your own work. Pull 50 to 100 real cases, including the ugly ones, and record the right answer for each. That labeled set is what practitioners call a golden dataset, and it is the most dependable answer to how to evaluate AI tools: the same yardstick, vendor after vendor.
Run it blind. Have the person who knows the work score the outputs without knowing which tool produced them. Count wrong answers, answers that need editing, and cases where the tool said it wasn't sure. A tool that flags its own doubt on 15% of cases can be more useful than one that is confidently wrong on 5%.
Price it and read the paper. Turn the trial usage into a twelve-month cost, then read the data processing terms, the service levels and the exit clause before anyone signs.
Two to four weeks is enough for most small and mid-sized teams. If nobody on staff has time to run it, outside help can, but keep the rubric and the test set in your hands. That's how Kief Studio approaches AI implementation work too: the client's data and the client's definition of success come first, and the tool choice comes after.
How do I evaluate AI personalization claims when every vendor says they use machine learning?
Personalization is where knowing how to evaluate AI tools pays off quickly, because the claims are the hardest to see through. "Machine learning" names a method, and when every vendor in a category uses the phrase, it tells you nothing about which one will move your numbers. Ask for the result instead, in a form you can check.
What is it compared against? Personalization should beat a simple rule, such as "show last month's best sellers" or "send the same email to everyone." Ask for results from a holdout group that got the non-personalized version.
Which signals does it use? Purchase history, browsing, location and time of day are different inputs with different privacy obligations. You should know which ones it reads and where they're stored.
How long until it works on your data? Personalization needs volume. A vendor should tell you how many customers or events it needs before results stabilize, and what it does before then.
If the answer to all three is another slide about the algorithm, treat the claim as unproven. The FTC's Workado order is a useful reminder that an AI accuracy or performance claim is supposed to have evidence behind it at the time it's made.
How do I assess whether a tool really learns during a vendor demo?
Ask the presenter to correct a wrong answer, then run the same input again. Then ask what just happened. Some tools retrain a model on your feedback, some store the correction as a rule or an example, and some change nothing until the next release. Each is fine if it's described honestly. Ask how long a correction takes to apply, whether one user's corrections affect other customers, and whether you can see and undo what the system learned.
How to vet an AI vendor as well as the tool
Knowing how to evaluate AI tools covers the product. The company behind it needs its own review, because a good tool from a vendor you can't hold accountable is still a risk. When people ask how to vet an AI vendor, these are the questions that do the most work, in roughly this order.
Who else touches the data? Most AI products call a model provider, a hosting company and often a few more services. Ask for the full sub-processor list. I wrote about why this matters in the sub-processor problem.
Can you switch the model without switching the tool? Products that let you bring your own AI key or choose the model give you a way out if a model gets worse or more expensive.
What happens when you leave? Ask for the export format, how long they keep your data after cancellation and how deletion is confirmed. Brian covers the details in what happens to your data when you cancel software.
Is the agent claim real? If the pitch is "autonomous agents," check whether the product plans and acts on its own or follows a fixed script. My guide to spotting agent washing has the test questions, and questions to ask an agentic AI provider goes further.
For Massachusetts businesses this isn't optional when personal information is involved. 201 CMR 17.03(2)(f) requires your written information security program to oversee service providers by "taking reasonable steps to select and retain third-party service providers that are capable of maintaining appropriate security measures to protect such personal information" and by "requiring such third-party service providers by contract to implement and maintain such appropriate security measures for personal information." An AI vendor that processes customer records is a service provider under that rule, so the security terms belong in the contract.
How to evaluate AI tools after they go live
The evaluation keeps going after you buy. Models get updated, your data changes, and a tool that passed in March can slip by September. The answer to how to evaluate AI tools after launch is the same test set: keep the golden dataset from the pilot and rerun it every quarter, or after any vendor release note that mentions a model change. I covered the warning signs in how to catch AI agent drift.
Ask before you buy whether the tool will tell you when performance drops. Useful answers include accuracy tracked over time, alerts when confidence falls, and a log of what the system did and why. For tools that take actions (sending a message, changing a record), you want an audit trail that shows what an AI agent did and why, alongside the count of tasks completed.
The NIST AI Risk Management Framework puts this under its Measure function, which treats performance as something you keep checking in the setting where the system is used. NIST says the framework, first released in January 2023, is being revised. Its approach to how to evaluate AI tools, with checks that continue while the system is in use, applies to a ten-person firm as much as a bank.
The vendor's incentive is to close the deal. The consultant's incentive depends on their billing model. Your team's incentive depends on who championed the project and what happens to their credibility if it fails.
The only reliable incentive is yours: does this tool make a specific part of your operation measurably better, at a cost you've validated, with risks you've identified and accepted?
If you can answer that with data instead of a demo, you're making a decision rather than being sold to.
And if you're still early in the process of figuring out what problems are even worth solving with AI, stop watching what everyone else is building and start with what's actually broken in your own operation, where the answers are quieter but much more useful.
The vendor demo is designed to show you the best case. Your evaluation should be designed to find the worst case. Ask for the failure modes before the features.
Write your evaluation criteria before the first vendor call. When the rubric exists before the pitch, confirmation bias has less room to operate.
Frequently asked questions about how to evaluate AI tools
How long should an AI tool evaluation take?
A meaningful evaluation (from initial vendor screening through hands-on testing with your own data) typically takes 2-4 weeks. Vendors who push for faster timelines are optimizing for their sales cycle, not your due diligence. The testing phase alone should run at least a week on production-representative data to capture enough variation in inputs and edge cases to trust the results.
What if the vendor won't let me test with my own data?
That's a disqualifying answer for most use cases. If a vendor insists on using only their demo environment or sample dataset, they either know the tool underperforms on real-world data, or they haven't built the infrastructure for customer trials. Either way, you'd be buying blind. Some vendors cite security concerns (which is fair), but the solution is a mutual NDA and a sandboxed environment, not skipping the test entirely.
Should I involve my engineering team in the evaluation?
Yes, but not only your engineering team. The best evaluations pair a technical reviewer (who can assess integration complexity, API quality, and architecture decisions) with an operational reviewer (who understands the actual workflow the tool needs to support). Engineers catch technical debt and operators catch usability gaps, so you need both perspectives before committing budget.
How do I compare two AI tools that both claim to solve the same problem?
Run both against the same set of your production data and score them on the four-question scorecard above. Weight the questions based on your priorities: a heavily regulated company might weight data handling at 40%, while a company with a complex existing stack might weight integration at 40%. The tool that scores higher on your weighted criteria is the better fit, regardless of which one had the more impressive demo.
How do you evaluate a vendor?
Judge the company and the product separately. For the company, look at its security program, who it shares your data with, how long it has been operating, and what the contract says about service levels, data return and exit. For the product, test it on your own data against a rubric you wrote before the demo. A strong product from a vendor that won't put data terms in writing is still a weak choice.
What are the different types of AI evaluation models?
The common methods are public benchmarks (standard test sets that compare models in general), task tests on your own labeled examples, human review by people who know the work, model-graded checks where a second model scores the first one's output, and live A/B tests against your current process. Benchmarks are useful for shortlisting. When you work out how to evaluate AI tools for your own business, the test on your own examples and the human review carry the most weight. Qurtoo's definition of evals covers the vocabulary.
How do I evaluate AI tools before buying them for my business?
Here's how to evaluate AI tools before buying, in short. Write the problem and the success number first, build a test set of 50 to 100 real cases, run each candidate tool on the same set, have someone who knows the work score the results without knowing which tool produced them, then compare twelve-month cost and data terms. The pilot steps above walk through it in order.
How do I evaluate AI tools for customer support before rolling them out?
Knowing how to evaluate AI tools for support comes down to realistic inputs. Use real tickets from the last few months, including angry customers, refund requests and questions your help docs don't answer. Score each draft reply for accuracy, tone and whether it made up a policy. Check what the tool does when it doesn't know, and whether a person approves replies before they go out. Start with drafts for your team to review rather than replies sent automatically, and widen from there only once the error rate is one you can live with.
What are the best practices for evaluating AI tools based on independent reviews?
Use reviews to build a shortlist, and make the decision on your own test. Check who wrote the review and whether the site earns money when you buy (affiliate links, sponsored rankings and paid placements are common). Give more weight to reviews that describe a specific workflow and a failure, and to published test results with a method you can read. Then follow the pilot steps on how to evaluate AI tools with your own data, because no reviewer has your edge cases.
How can small businesses tell whether an AI tool is trustworthy and transparent?
For a small business, how to evaluate AI tools for trust comes down to four questions: which model it runs on, how accuracy was measured, whether your data trains anyone's model, and how you get your data back if you leave. Transparent vendors answer in writing. The Stanford transparency index above shows that disclosure varies widely even among the largest model developers, so a vendor that can tell you which model it uses and what that developer publishes is giving you something real.
How do I know if a vendor's efficiency claims are realistic?
Part of how to evaluate AI tools is checking the math behind a savings claim. Ask where the number came from: which customers, which tasks, measured how and over what period. Then time the task yourself, before and during the pilot, including the time spent reviewing and fixing the AI's output. Savings claims that leave out review time are usually the ones that don't hold up. If the vendor's figure came from a customer with ten times your volume, scale it down before you put it in a budget.
How do IT teams evaluate AI software tools?
IT teams usually add three checks to the business review: how the tool signs users in (single sign-on, roles, offboarding), where data flows and is stored, and what it needs to connect to existing systems. For IT, how to evaluate AI tools is largely a question of what the tool can reach. A tool that needs broad access to email, files or a CRM should get the same review as any new system with that access.
How to evaluate AI tools for marketing and advertising?
Judge them on output you would actually publish. Give each tool the same brief, your brand guidelines and a few past campaigns, then have the person who approves your marketing score the drafts for accuracy, voice and claims you can't back up. For ad tools, ask how results are measured and whether the vendor's reporting can be checked against your own analytics. Keep a person approving anything that goes out under your name.
How to evaluate AI tools for sales teams?
Test them on your real pipeline: past call notes, actual account records and the follow-ups your best rep wrote. Check whether the tool invents details about a prospect, how it handles a record with missing fields, and whether reps keep using it after the first two weeks. Adoption during the pilot is part of the result. A sales tool that reps quietly stop opening has failed the evaluation even if its drafts were good.
How to evaluate AI tools for analytics before a large rollout?
Run the pilot with a small group that includes your most skeptical analyst, and check every answer the tool gives against a figure you already trust. Ask how it handles permissions, so a user only sees data they are allowed to see, and what it costs per user or per query at full scale. If the tool can't show where each number came from, wait before rolling it out to hundreds of people.
Is learning how to evaluate AI tools worth it for a small team?
Yes, because small teams feel a bad purchase more. A two-person firm can still run a small version of the pilot in this article: twenty real cases, one person scoring, and a written walk-away rule. That takes a few hours, and it costs far less than a year of a subscription that doesn't fit how you work.
Nearly 82% of the smallest businesses not planning to use AI say it isn't applicable to them. Here's how to find where AI actually fits in your business, starting with the work you already do every week.
AI pilots stall before production for boring reasons: no owner, no definition of done, no data path, no kill switch. CISA 1 May 2026: start low-risk. NIST AI RMF: Govern, Map, Measure, Manage.
AI agent governance fails when you approve each click and miss the path. Five in-policy refunds can still empty the drawer. Store intent, cap the run, gate pay/send/delete.