Data Lineage: Knowing Where Your Numbers Actually Come From
Poor data quality costs organizations an average of $12.9 million a year, according to Gartner, and most of that damage starts with a number nobody can trace. Data lineage follows a figure from its point of origin through every ingest, transform and model until it lands on a report.
The short version: data lineage is the record of where a number came from and every step that changed it before it reached your report. Start with your ten most important numbers, write down the source, the calculation and the owner for each, and fix the ones nobody can trace before you build reports or AI on top of them.
Name the source system for each key number.
Write the definition in one sentence: what's counted, when, and minus what.
Give each number one owner and one source of record.
Note every transform between source and report.
Prefer tools that record data lineage automatically as they run.
Poor data quality costs organizations an average of $12.9 million a year, according to Gartner, and most of that damage starts with a number nobody can trace. Data lineage is the practice of following a figure from its point of origin through every ingest, transform, and model until it lands on a report, so you can prove where it came from and trust what it says. Without lineage, a wrong number looks exactly like a right one.
Data lineage answers a deceptively simple question: where did this number actually come from?
I study behavioral psychology, and one pattern shows up in almost every business I talk to. People trust a number in direct proportion to how confidently it is presented, not to how carefully it was produced. A clean chart in a boardroom carries more authority than the messy pipeline behind it deserves. Lineage is the discipline that closes that gap.
What data lineage actually means
The DAMA Data Management Body of Knowledge, the field's standard reference, describes lineage as the pathway along which data moves from its point of origin to its point of usage, sometimes called the data chain. In plainer terms, data lineage is a map of every place a value has lived and every operation that touched it along the way.
Provenance is the close cousin of lineage. Provenance records where data originated and what was done to it, while lineage emphasizes the movement and transformation across systems. In practice the two overlap, and you want both: the birth certificate and the travel history for every figure you rely on.
The reason this matters is that a modern number is almost never raw. It is filtered, joined, deduplicated, currency-converted, rounded, and reshaped a dozen times before a human sees it. Each of those steps is a place where the meaning can quietly shift.
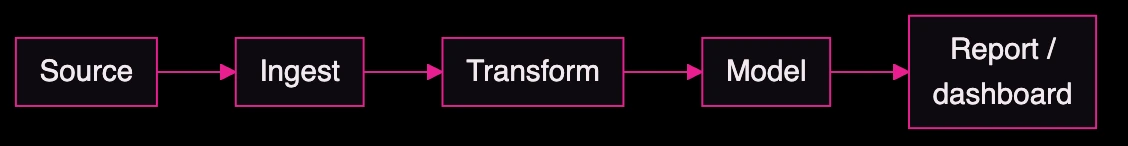
A minimal lineage chain: every arrow is a place a number can change meaning without anyone noticing.
Why an untraceable number is a business risk
The most expensive data errors are the ones that look perfectly reasonable rather than wrong. Thomas Redman, writing in MIT Sloan Management Review, estimates that bad data costs most companies 15 to 25 percent of revenue, largely because people spend their days accommodating errors: correcting them, double checking them, and cleaning up the decisions made on top of them.
The famous cautionary tale here is an economics paper. In 2010, economists Carmen Reinhart and Kenneth Rogoff published research arguing that national growth collapses once public debt passes 90 percent of GDP, and the finding was cited around the world to justify austerity policy. A graduate student who tried to reproduce it discovered the headline came partly from an Excel formula that silently excluded five countries from an average. Correcting that range reference, along with two other problems in how the data was selected and weighted, moved the reported growth figure from negative territory to positive.
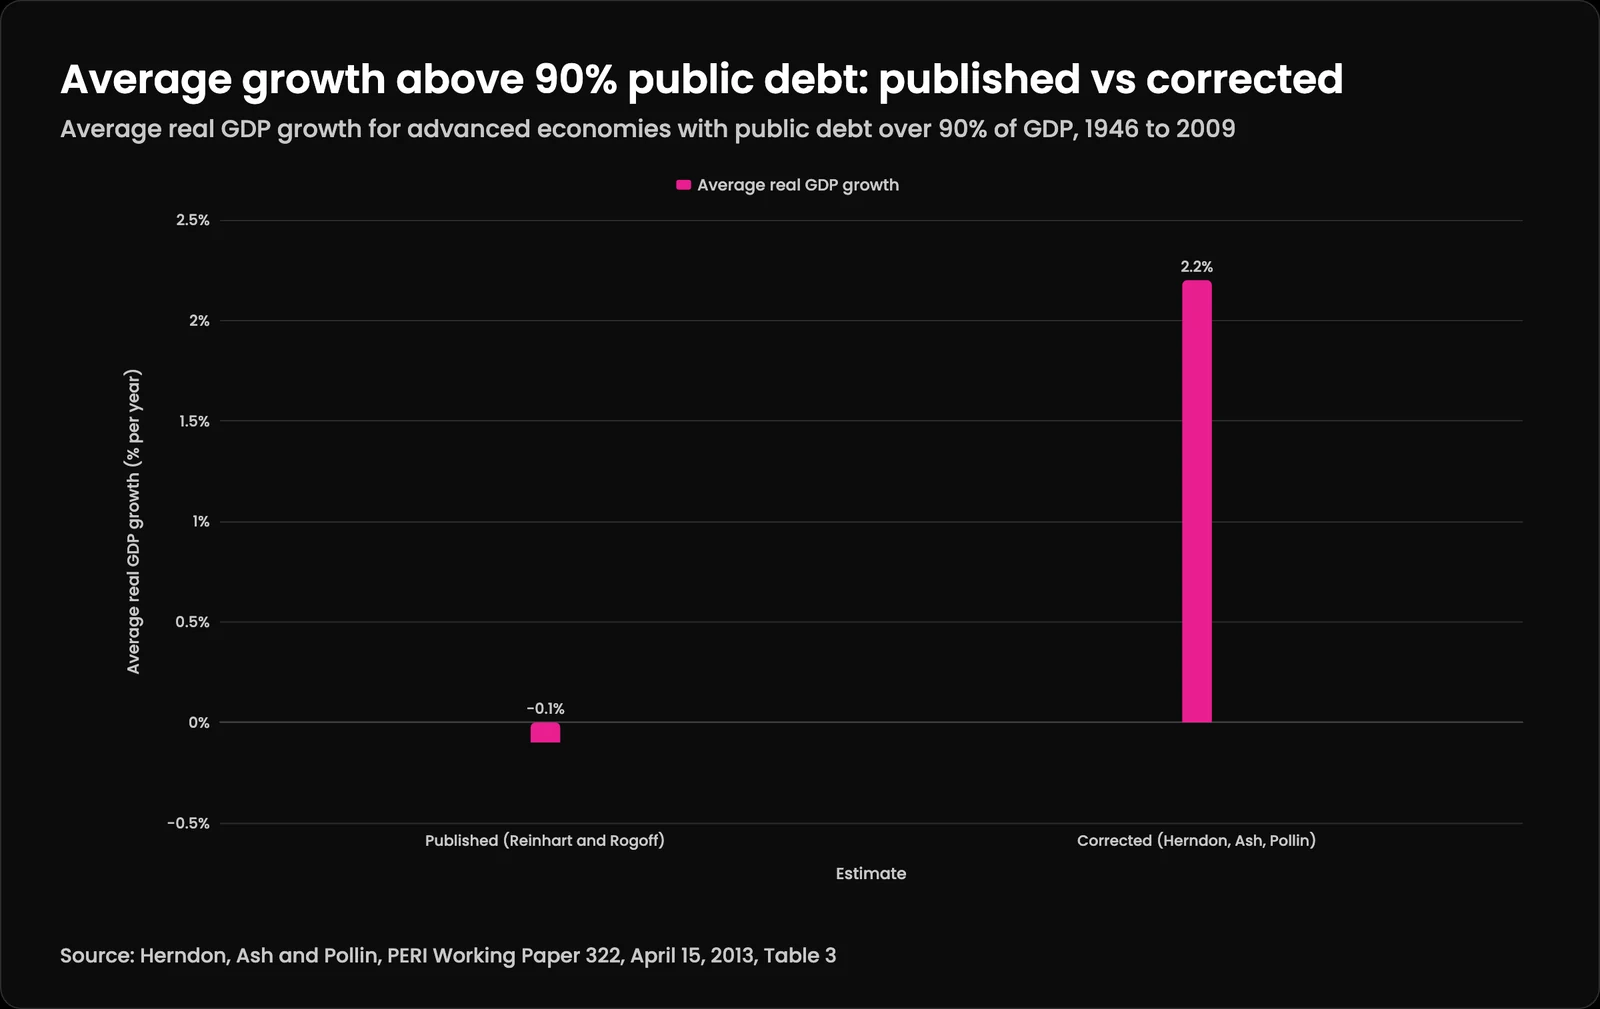
The student was Thomas Herndon at the University of Massachusetts Amherst. His critique with Michael Ash and Robert Pollin, PERI Working Paper 322 (April 2013), found that the spreadsheet averaged rows 30 to 44 instead of 30 to 49, leaving out Australia, Austria, Belgium, Canada and Denmark. With that and two methodological issues corrected, average growth for countries above 90 percent debt was 2.2 percent, not the published negative 0.1 percent. Reinhart and Rogoff acknowledged the spreadsheet error.
With the spreadsheet range and two methodological issues corrected, the published -0.1 percent became 2.2 percent, an error data lineage is built to catch.
Average growth above 90% public debt: published vs corrected (Herndon, Ash and Pollin, PERI Working Paper 322, April 15, 2013, Table 3)
Estimate
Average real GDP growth
Published (Reinhart and Rogoff)
-0.1%
Corrected (Herndon, Ash, Pollin)
2.2%
Nobody in that chain was careless in an obvious way. The spreadsheet ran, the chart rendered, the number was quoted. What was missing was lineage: a way to trace the published figure back to the exact cells that produced it before the world acted on it.
The lesson is that any number without a traceable path is a claim on faith, whatever tool produced it. A chart cannot show you the rows it dropped, and a dashboard rarely tells you which export it read or how old that export is. The polish of the presentation actively hides the fragility of the pipeline underneath.
Small businesses run the same risk at smaller scale every week: a revenue figure that double counts refunds, a lead count that includes bot traffic, or a churn rate built on a stale export. As I have written in disconnected data is more expensive than missing data, the bigger danger is a confident number that is wrong, more than a missing one.
Where does a number come from? Tracing the chain
A useful lineage map has five stages, and each one deserves a name and an owner. The stages are source, ingest, transform, model, and report. If you cannot say who owns each stage for a given metric, you do not yet have lineage, you have a habit.
Source is where the value is born: a payment processor, a form submission, a point of sale system, a sensor. Ingest is how it enters your world, usually an export, an API pull, or a sync. Transform is every calculation and cleanup applied to it. Model is where it joins other data into a shared shape, like a customers table or a monthly summary. Report is the dashboard, invoice, or slide where a human finally reads it.
The value of naming the stages is that errors become locatable. When a figure looks wrong, you do not argue about it, you walk the chain. Most of the time the fault is a single transform that changed last quarter, or a source that started sending a new field format. This is the same discipline I described in three layers of analytics, where knowing which layer produced a number tells you how much to trust it.
Column level detail is where lineage earns its keep. Knowing that a report depends on a customers table is helpful. Knowing that the churn figure specifically depends on one date field, filtered one way, joined to one status column, is what lets you fix a problem in minutes instead of a week. Good lineage tracks not just which tables feed a number, but which fields and which rules.
There is also a human layer that tools miss. Two teams can pull a metric called revenue and mean genuinely different things: one nets refunds, one does not. Lineage that captures the definition, not just the plumbing, prevents the meeting where two correct dashboards disagree and nobody can say why.
Lineage is the prerequisite you cannot skip before AI
Every business I meet wants to add AI on top of its numbers. Very few can tell me where those numbers came from, and that ordering is backward. A model trained or prompted on untraceable data inherits every silent error in the pipeline, then presents the result with even more polish and even less accountability.
This is why I keep returning to the point that data governance is the real prerequisite for AI. Lineage is the concrete, checkable core of that governance work. It is what lets you answer the only question that matters when an AI system produces a figure: on what, exactly, was this based?
The failure mode is well documented. When teams rush to layer intelligence onto data they do not understand, the project stalls in ways I described in AI without the data. The demo works, the production system does not, and the root cause is almost always upstream: a source or transform nobody could vouch for. Trustworthy AI is downstream of trustworthy lineage.
How to build lineage without a data engineering team
You do not need a governance platform to start. You need to make the invisible visible. The first move is a metric dictionary: for your ten most important numbers, write one plain sentence each describing the source, the transform, and the definition. Revenue means what, counted when, minus what.
The second move is to give each critical number a single owner and a single source of record, rather than the sprawl I described in your data lives in four SaaS tools and a group chat. A number with two sources will eventually disagree with itself, and you will lose a morning reconciling two truths that were never the same measurement.
The third move is to prefer systems that record lineage as a byproduct of how they run. This is the same principle as building software that is secure by construction: the property you want should fall out of good engineering, not sit in a separate manual you never open. When the pipeline documents itself, lineage stops being a project and becomes a default.
For a structured starting point, the sequence I lay out in data governance for growing companies works well: inventory what you have, name owners, then document the flows for your highest stakes metrics first. You are not trying to map everything. You are trying to make your load bearing numbers defensible.
What is an example of data lineage?
Take the monthly revenue figure a twelve-person services firm shows its partners. Here is its data lineage, written out the way I'd want it in a metric dictionary:
Data lineage for one number: monthly revenue
Stage
What happens
Owner
Source
Card payments in the payment processor; checks recorded in accounting
Office manager
Ingest
Payment export downloaded as a CSV on the first business day
Office manager
Transform
Refunds subtracted, processor fees left in, checks added from the ledger
Bookkeeper
Model
Joined to the client list so revenue can be shown by service line
Bookkeeper
Report
Partner dashboard, "Revenue (net of refunds, gross of fees)"
Managing partner
Now suppose the dashboard shows revenue up 9% and the bank balance doesn't agree. With this data lineage on paper, the check takes minutes: someone looks at the transform row and sees that a refund batch posted late, so last month subtracted it twice and this month not at all. Without it, three people each pull their own export and spend a morning arguing about which one is right.
Notice the label in the report row. Writing "net of refunds, gross of fees" on the dashboard itself is the cheapest data lineage there is, and it settles half the disagreements before they start.
Business data lineage, technical lineage and process lineage
People use "data lineage" for three related records, and it helps to know which one you're asking for.
Technical data lineage follows data through systems: which tables, columns, jobs and queries produced a value. It's what engineers use to find the transform that broke.
Business data lineage follows meaning: the business definition of each number, who owns it, and which business terms map to which fields. It's what tells a finance lead that "revenue" on the sales dashboard and "revenue" in the board deck are, or aren't, the same thing.
Process lineage follows the work: which business steps create or change the data, such as a quote approved, an invoice issued, a refund granted. It connects a number back to the decision that produced it.
A small business usually needs business data lineage first, because most of its disagreements are about definitions rather than pipelines. Technical data lineage matters more as the number of systems grows. Brian's post on the client who wanted a dashboard but actually wanted a decision is a good reminder to start from the decision a number supports, then trace back.
What is a lineage and provenance graph?
Data lineage tools usually store what they learn as a graph. Each dataset, table or file is a node, each job or query that reads and writes is another node, and the edges show what fed what. Walk the graph upstream from a report and you reach every source it depends on. Walk it downstream from a source and you see every report a change will touch.
Two open standards describe these graphs. The W3C's PROV family (2013) defines a general model for provenance: entities, the activities that produced them, and the agents responsible. OpenLineage, a graduated project of the LF AI & Data Foundation since 2023, defines how data jobs report at run time which datasets they read and which they wrote, so the data lineage graph builds itself as the pipelines run.
The same idea applies to AI agents that take actions. An agent's log of what it read, what it decided and what it changed is lineage for its work, which is why an audit trail for AI agents is worth asking for before you let one touch your records.
How do you measure data lineage?
A few metrics tell you whether data lineage is real or aspirational:
Coverage. Of your ten or twenty most important numbers, how many have a written source, definition, transform list and owner?
Depth. For each, does the data lineage stop at the table, or does it reach the specific fields and filters?
Automation. What share of your pipelines record lineage themselves, versus a document someone has to remember to update?
Freshness. When was each lineage record last checked against what the pipeline actually does?
Time to trace. When a number is questioned, how long does it take to find the step that produced it? If the answer is minutes, the lineage is working. If it's days, the lineage lives only in someone's head.
Time to trace is the one I'd track first. It's easy to measure, it moves quickly once you start, and it's the number that tells you whether data lineage is saving anyone a morning.
How data lineage improves trust in financial reports
Financial reports are where an untraceable number costs the most, because people act on them: a loan application, a tax filing, a decision to hire. Data lineage lets you show, for each figure, which ledger accounts it came from, which adjustments were applied and who approved them. That is the same question an auditor or a lender will ask.
Keep calculations in the system of record wherever you can, and keep AI tools on the reading and summarizing side rather than the arithmetic. Qurtoo's playbook on bank reconciliation with AI, without letting it do the math shows the pattern: the AI matches and explains, and the totals come from the books. When a figure in a report traces to a ledger and not to a chat window, its data lineage holds up.
Lineage, retention, and what you choose to keep
Tracing where a number comes from naturally surfaces a second question: does it need to exist at all? Many pipelines carry sensitive raw records for years purely because nobody ever mapped the flow and asked. Lineage gives you the map to decide.
Once you can see the full chain, you can often cut it short. A metric that only needs a monthly total does not require you to retain every underlying transaction forever. This connects directly to the argument that the cheapest way to protect data is to not keep it: lineage tells you which raw inputs you can safely age out once the derived number is settled and trusted.
That is the quiet payoff. Lineage is usually sold as a data quality tool, and it is one. It is also a risk reduction tool, a cost control tool, and the foundation that makes automation and AI trustworthy instead of merely impressive. Kief Studio's data engineering work usually fixes this plumbing first, because the systems that last are the ones you can explain.
Data lineage is a map of where a number comes from and everything that happened to it on the way to your report. It traces a value from its original source, through each ingest and transformation, to the dashboard or invoice where you finally read it, so you can prove the figure is correct.
What is the difference between data lineage and data provenance?
Provenance focuses on origin and history: where the data was born and what was done to it. Lineage emphasizes movement and transformation across systems: the full path and every operation along it. In practice they overlap heavily, and a healthy data practice tracks both.
Why does data lineage matter before adding AI?
An AI system built on untraceable data inherits every silent error in the pipeline and then presents the result with more polish and less accountability. Lineage lets you answer the essential question behind any AI output: what data was this based on? Without that, trustworthy AI is not possible.
How do I start tracking data lineage in a small business?
Begin with a metric dictionary for your ten most important numbers, writing one sentence each for the source, transform, and definition. Give each critical number a single owner and a single source of record. Prefer tools that record lineage automatically as part of how they run.
What does a wrong dashboard number actually cost?
Gartner puts the average annual cost of poor data quality at $12.9 million, and MIT Sloan research estimates bad data costs most companies 15 to 25 percent of revenue. The larger cost is usually invisible: confident decisions made on figures that quietly excluded, double counted, or misdefined the underlying data.
What does data lineage do?
Data lineage records the path a value takes from its source to the place you read it, including every calculation along the way. That lets you trace a wrong number to the step that broke it, see which reports a change will affect before you make it, and show an auditor, a lender or an AI reviewer exactly what a figure is based on.
What is the best data lineage tool?
The best data lineage tool is the one that records lineage automatically from the systems you already run, at the level of detail you need, and that your team will actually open. For many small businesses that's the lineage view built into their data warehouse or transformation tool, plus a written metric dictionary. Larger teams often adopt a catalog that reads OpenLineage events. Test any candidate by asking it to trace one disputed number end to end.
What does Gartner say about data lineage?
Gartner's data quality research puts the cost of poor data quality at at least $12.9 million a year on average, from 2020 research, and says 59% of organizations don't measure data quality. In February 2025 Gartner predicted that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data, and it named missing metadata as one reason organizations can't assess readiness. Data lineage is a large part of that metadata. In January 2025 Gartner also published its first Magic Quadrant for data and analytics governance platforms, a category where lineage is a core feature.
What are the four types of analytics according to Gartner?
Gartner names four types: descriptive (what is happening), diagnostic (why did it happen), predictive (what will happen) and prescriptive (how can we make it happen). Each one builds on the last, so a data lineage gap in the descriptive numbers carries straight through to the predictions and recommendations built on them.
Are there open source tools for data lineage and metadata management?
Yes. OpenLineage is an open standard and API for collecting lineage as jobs run, and Marquez, also an LF AI & Data project, is its reference implementation for collecting and visualizing that metadata. Several open source data catalogs and orchestration tools can read or emit OpenLineage events. Open source lowers the license cost of data lineage, though someone still has to run and maintain it.
What is business data lineage?
Business data lineage connects a number to its meaning: the business definition, the owner, the rules applied and the business terms used for it in reports. It answers "what does this number mean and who decides" rather than "which table did it come from." For most small businesses it's the most useful place to start.
What is process lineage?
Process lineage traces data back to the business steps that created or changed it, such as an order placed, a discount approved or a refund issued. It helps when a number is technically correct but reflects a process problem, like refunds approved outside the normal workflow.
Worcester life sciences startups added jobs in 2025 while Massachusetts biopharma employment fell 3.1%. The systems a twenty-person lab sets up now are exactly what its first audit will inspect.
The safest record is the one you never collected. Data minimization treats retention as liability, not free storage, and builds deletion in as a default.
You cannot bolt intelligence onto a business with no clean, connected data underneath. Why “just add AI” quietly fails, and what AI-ready data actually means.